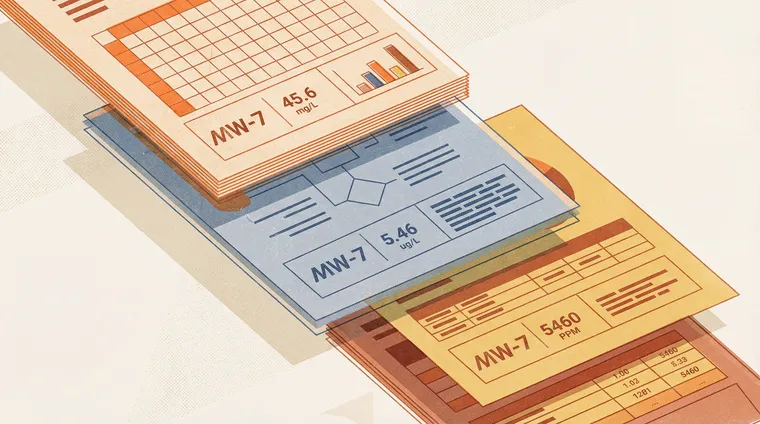
A tank-pollution record sits somewhere in a 14,000+ page site file. An indemnity clause that allocates the cost ends mid-sentence at the bottom of one page and finishes on the next.
Environmental decisions hinge on details like these: a qualifier in a lease, a detection limit in a lab table, a decimal point in a hatched cell. Generic AI tools are built to produce a fluent summary, and fluency is where the details go missing.
The challenge of detail at scale
Consumer AI tools work from whatever fits in a context window. A paid ChatGPT Plus or Claude Pro account caps file size, extracts text from PDFs without reading scanned tables as images, and keeps no memory of the site between sessions. On a portfolio with decades of records, the tool sees a sample of the file and writes as if it saw all of it.
Three failure modes show up repeatedly in site work:
- Partial retrieval. The model finds the three most similar passages and stops. The fourth passage, which qualifies or contradicts the first three, never enters the answer.
- Broken continuations. A sentence, table, or clause that spans two pages gets read as two unrelated fragments.
- Silent table errors. A value misread from a scanned lab report enters the analysis with no flag, and every downstream exceedance calculation inherits it.
Each of these produces an answer that reads well and cannot be defended under cross-examination.
Semantic search finds what the wording hides
Keyword search fails when the record does not use your words. A 1980s report may say "product loss" where a later report says "release," or "underground storage" where you searched "UST." Semantic search in Statvis matches on meaning, so if you have a question, Statvis surfaces the relevant passages to allow for review.
Every result cites the document, page, and passage. You verify the claim by clicking through to the source, which keeps the AI in the role of finding evidence while the professional decides what it means.
Exhaustive search answers the question "is there anything else?"
Ranking the best matches is the right behavior for a quick lookup and the wrong behavior for a liability question. When the question is "every release reported at this site" or "every reference to this responsible party," the missing result matters more than the ten you already have.
Exhaustive search works through the full set of candidate passages rather than stopping at the top results. It removes duplicates, gives every document a fair share of the results so one long report cannot crowd out a short letter, and keeps strong semantic matches that keyword matching would have dropped. When a passage continues on the next page, the continuation is read before the conclusion is drawn.
For a transaction or a regulatory closure package, this changes the working question from "what did the search return?" to "what did the search cover?"
Envirobench keeps the details honest
Claims about accuracy need a way to be tested. We built Envirobench, a benchmark for the document-reading tasks environmental work depends on, including reading values from scanned lab tables and placing sample locations on site plans.
Envirobench uses cells and locations that people have checked and corrected, so it measures the errors that matter. Each run records the prompts, settings, cost, and case-level results, which lets us compare any model change against the same reviewed set before it reaches a client site.
The results are a reason to keep people in the loop. On a challenge set built from values reviewers had corrected, current vision models read a majority of table cells exactly and still missed a meaningful share, including values that repeated a known wrong production read. Location placement was weaker still. A model that is right most of the time and wrong without warning needs a review gate, so Statvis routes disagreements and risky values to a reviewer before they reach the data.
What this means for environmental professionals
- Answers carry citations to the exact page and passage.
- Searches report their coverage, so a gap is visible before it appears in a deliverable.
- Table values that fail a check go to a person, and the benchmark tells us where those checks need to be stricter.
- Model changes are tested on reviewed data before they touch your site.
Site history is never simple. Records go missing, pages split mid-sentence, and a scanned cell can hide a decimal. Statvis does not remove that complexity. It makes sure the details are found, checked, and cited, so your professional judgment rests on the complete record.